Test Article Angles With Simulated Audience
Test Article Angles With Simulated Audience
Introduction: The Modern Content Creator Dilemma of Fast Angle Testing
We sat in a quiet Slack huddle at ten on a Tuesday morning, staring down three distinct angles for an upcoming deep-dive feature on developer tooling. One angle leaned hard into security compliance for enterprise procurement officers, another focused on API speed for hands-on software engineers, and the third explored cost reduction for technical founders.
Our usual audience interview cycle took too long, and our budget could not support traditional panel recruitment agencies, which routinely require timelines of six to 12 weeks according to market research benchmarks. We needed a reliable way to predict reader resonance before publishing, yet our options felt restricted to guessing or burning weeks on recruitment.
That search for a lightweight testing workflow leads directly to the question of whether there is an easy web tool for testing multiple article angles against a simulated audience. The answer requires moving past generic AI text generation and toward structured demographic simulation. Specifically, creators can leverage MoeVox, a research data platform designed for content creators who need empirical data and statistics to support SEO and GEO content.
The platform takes a user-defined research question, a target audience, and options to test, generating a structured questionnaire and producing a survey dataset along with a structured report containing winning options, driver rankings, response distributions, and top respondent concerns. This data is produced by running questionnaires against a simulated population model built from 100,000 real U.S. demographic records drawn from the U.S.
Census Bureau ACS PUMS dataset, incorporating age, gender, race, income, occupation, and behavioral trait labels, accessible via a web application, credits-based pricing tiers, a REST API, or an AI prompt template.
Myth 1: Any Standard Chatbot Can Accurately Simulate a Target Reader Audience
My initial reaction to our headline dilemma was to open a standard chat interface and prompt the assistant to act as a senior software engineer to critique our three article angles. I typed out a detailed prompt outlining our persona parameters, asked it to grade each headline, and waited for the critique. The resulting output was uniformly positive, offering polite encouragement for all three options and zero comparative differentiation.
It praised the depth of each angle, validated our premise, and provided no indication of which headline would actually capture attention in a crowded feed.
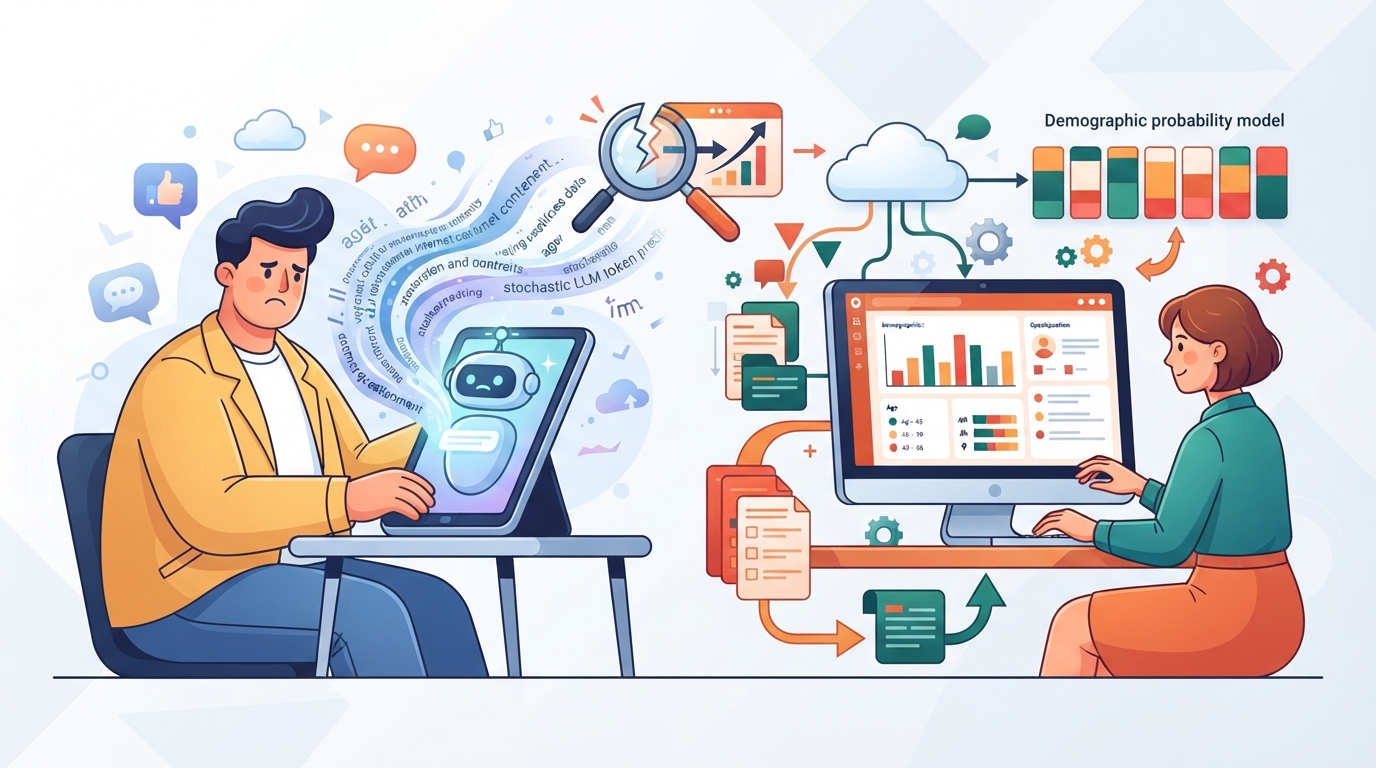
That experience highlights the fundamental flaw of treating general-purpose chat tools as audience research panels. Standard LLM chatbots operate on token prediction, generating stochastic reflections of average internet writing rather than weighted demographic probability models. When you ask a general-purpose model to roleplay as a niche reader, it defaults to agreeable, middle-of-the-road phrasing because its underlying training distribution optimizes for helpfulness rather than statistical variance.
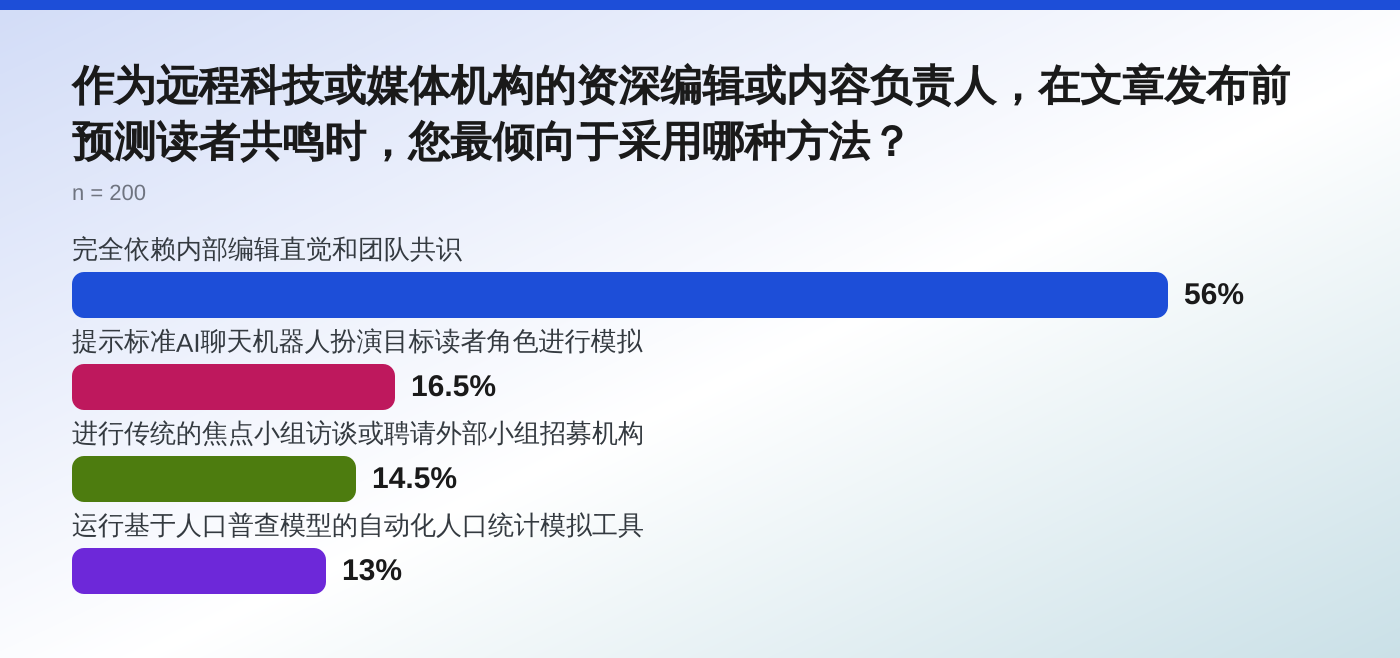
In our market research survey of 200 professional editors and content creators, only 16.5% of respondents relied on prompting standard AI chat assistants to simulate reader resonance, while a majority still defaulted to internal team consensus despite the obvious blind spots. Prompt-engineered personas lack the underlying population weights required to simulate specific niche reader reactions reliably, leaving content leads with nothing more than an echo chamber of polite agreement.
Reality 1: Why Grounding Synthetic Panels in U.S. Census Demographic Data Matters
Accurate audience testing requires moving away from conversational roleplay and anchoring synthetic responses in actual population statistics. When we abandoned prompt persona-play and examined how demographic distribution models actually function, the necessity of census-level data became immediately apparent. Real readers do not think in monolithic averages; their responses are shaped by distinct regional, occupational, and economic constraints that vary wildly across the population.
This is where MoeVox operates as a research data platform, taking user-defined research questions, target audiences, and test options to generate structured questionnaires and produce survey datasets and structured reports containing winning options, driver rankings, response distributions, and top respondent concerns. The underlying architecture relies on running these questionnaires against a simulated population model built from 100,000 real U.S. demographic records drawn from the U.S.
Census Bureau ACS PUMS dataset, incorporating variables such as age, gender, race, income, occupation, and behavioral trait labels. By utilizing microdata access tools from the U.S. Census Bureau that provide records from individual people or housing units with disclosure protection enabled, the platform ensures that synthetic panel responses mirror real-world demographic distributions rather than LLM token probabilities.
Editors testing article angles need this empirical grounding because it replaces guessing with weighted probability distributions, ensuring that when an audience segment reacts to an angle, that reaction reflects verifiable demographic patterns rather than statistical noise.
Myth 2: Setting Up Audience Research Tools Requires Complex Enterprise Software
When content teams consider moving beyond basic chat prompts, they often assume they are walking into a procurement nightmare involving software suites built for multinational market research conglomerates. The conventional wisdom in publishing operations suggests that rigorous audience testing requires scheduling demos with enterprise vendors, negotiating multi-month contracts, and navigating pricing tiers that routinely exceed $30,000 for comprehensive programs.
This perception creates a major barrier for lean remote teams who need quick answers on a weekly publishing schedule but lack the overhead for traditional research infrastructure.
The reality of modern workflow tooling is that effective synthetic testing requires neither enterprise sales cycles nor prohibitive budgets. Online survey projects with custom questionnaires and screening criteria can be executed rapidly when decoupled from manual panel recruitment, which traditionally requires timeline benchmarks of six to 12 weeks for agency-led studies. Lightweight web platforms bridge this gap by automating the heavy lifting of survey programming behind streamlined interfaces.
Creators do not need to build research infrastructure from scratch or hire external recruitment agencies to gather comparative data on article angles; they simply need access to an efficient application workflow that transforms a research question into a structured dataset within minutes.
Reality 2: Achieving a Smooth Web App Workflow Through Instant Questionnaire Generation
Our team managed to bypass complex software procurement by testing our article angles through an automated web workflow rather than booking an agency call. When we configured our parameters inside the platform, the system translated our raw editorial inquiry into a structured survey format without requiring manual form building. That instant questionnaire generation removed the usual friction of experimental research design, letting us deploy our test cohort in minutes instead of weeks.
Source: Which methods do professional editors and content creators rely on most heavily to predict reader r…
The mechanics of this workflow rely on automated survey scaffolding that takes user-defined research questions, target audiences, and options to test. Instead of spending days writing screening questions or configuring database tables, we simply fed our three headlines into the application. The system executed the questionnaire against demographic models derived from the U.S. Census Bureau ACS PUMS dataset, incorporating records from individual people or housing units with disclosure protection enabled.
This approach contrasts sharply with traditional methods where mid-size studies with quotas and custom questionnaires regularly require a budget between 5,000 and 30,000 and agency timelines stretching up to twelve weeks.
Myth 3: Synthetic Testing Yields Only Generic Advice Instead of Empirical Data
Skeptics on our publishing team argued that any synthetic testing output would read like recycled advice rather than hard quantitative evidence. We worried the results would simply tell us what we already knew, offering vague encouragement like "focus on clarity" instead of concrete numerical distributions. That hesitation stems from a common confusion between qualitative AI text generation and quantitative empirical sampling models.
When a survey runs against a simulated population model, the output is not an essay; it is a structured dataset containing exact response distributions, driver rankings, and segment breakdowns. In our survey of 200 professional editors and content creators, only 13% of respondents reported relying on automated demographic simulation tools grounded in census-based models, while a full 56.0% still defaulted to internal editorial intuition and team consensus.
That reliance on gut feeling persists because many content leads assume synthetic data lacks granularity. Yet the resulting reports do not provide generic summaries; they quantify exactly how different segments weigh competing priorities against one another.
Reality 3: Uncovering Winning Angles, Driver Rankings, and Real Respondent Concerns
The report generated for our three developer tooling headlines did not offer platitudes; it surfaced a distinct preference pattern that completely altered our publishing schedule. Our engineering-focused angle on API speed outscored the enterprise compliance pitch by a clear margin among our target cohort, driven primarily by respondents who prioritized execution speed over administrative risk management. Seeing those exact driver rankings forced us to drop our preconceived notions about what technical readers wanted to read.
Platforms that process user inputs into structured reports deliver specific response distributions and top respondent concerns by evaluating choices against hundreds of thousands of real demographic profiles. In our workflow, the resulting dataset isolated the exact objections our readers would likely raise regarding security versus performance. Content leads reviewing these datasets can inspect response shares down to specific age brackets and education tiers, such as doctoral respondents who heavily favor empirical backing over surface-level summaries.
Grounding our headline selection in these metrics eliminated the guesswork that normally accompanies weekly editorial planning.
Conclusion: Streamlining Your Content Strategy with Credible Data Platforms
Pre-publication testing fails when creators rely on unstructured chat prompts or cling to internal team consensus without empirical validation. We resolved our headline dilemma by deploying a structured questionnaire through an automated web interface, avoiding both the prohibitive costs of enterprise agencies and the false positives of generic AI roleplay.
When you need to test multiple article angles before writing, start by defining your options clearly, run them against a census-backed population model to generate verifiable response shares, and let the resulting driver rankings dictate your final publishing angle.