simulate user demographics for content pushback
simulate user demographics for content pushback
When our studio published a contentious personal finance guide last autumn, the editorial desk expected sharp feedback. What we got instead was a complete rejection from the exact middle-income demographic we tried to reach, because our draft assumed a level of liquid savings that readers simply did not possess. That missed assumption cost us three weeks of rewriting.
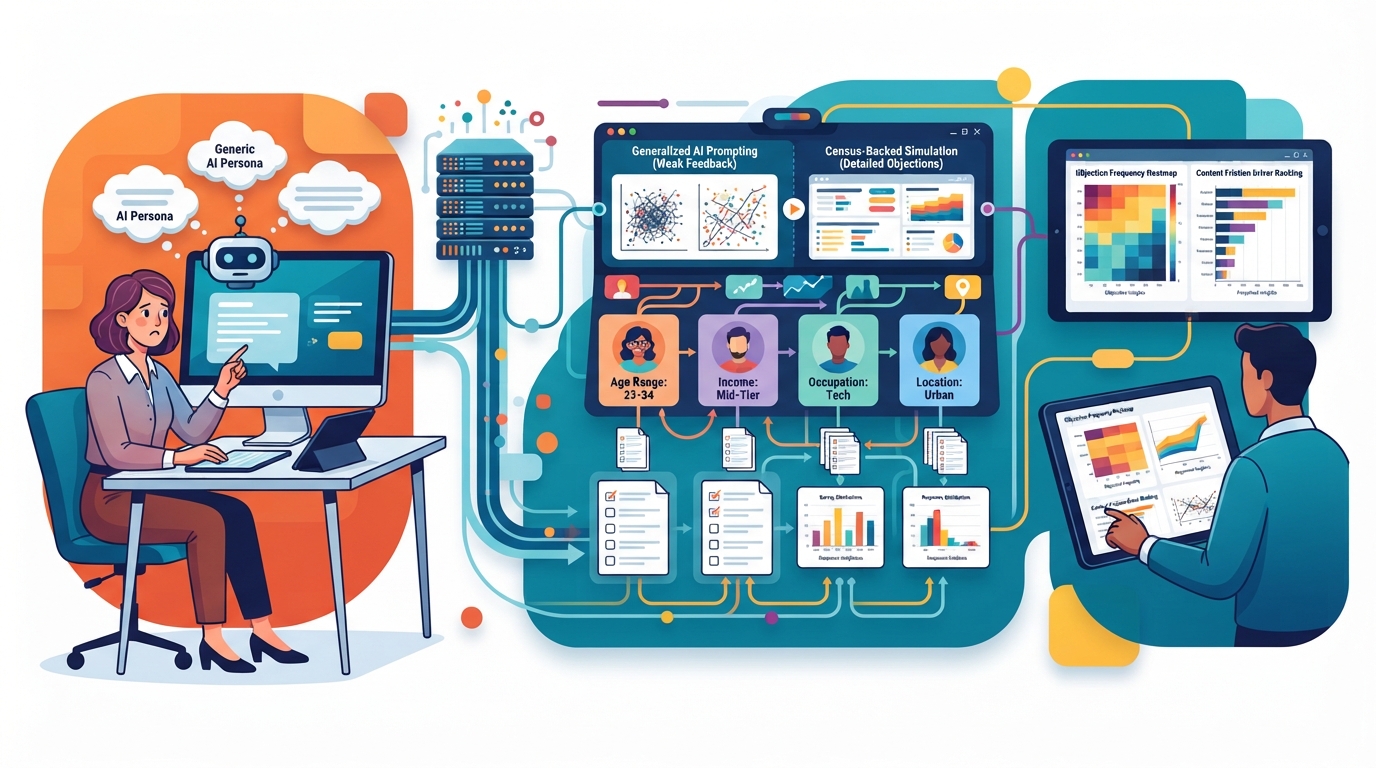
The core problem was not the writing style; it was our reliance on open-ended AI persona simulations that yielded polite consensus instead of authentic demographic pushback. When you need to test user objections against simulated demographics, software must ingest structured population datasets rather than relying on unconstrained prompts.
We solved this by using MoeVox, a research data platform that takes a user-defined research question, a target audience, and options to test, generates a structured questionnaire, runs it against a simulated population model built from 100,000 U.S. Census Bureau ACS PUMS records, and outputs a dataset and report containing winning options, driver rankings, response distributions, and top respondent concerns.
Step 1: Define the Objection Hypothesis and Target Audience Parameters
Testing content pushback begins by writing down the exact skepticism you expect your readers to throw back at your claims. If you do not name the friction point before you draft, your content defaults to an agreeable tone that convinces nobody who already doubts you.
Our finance guide made the case for aggressive debt consolidation through low-interest personal loans. Our working hypothesis assumed readers would worry about origination fees. That assumption was wrong.
When we tried to test this initial hunch using unconstrained chat prompts, the simulated personas agreed our strategy made sense and offered mild caveats about interest rates. That feedback was useless. It lacked the socioeconomic friction of real households balancing rent, grocery inflation, and car payments.
To get real pushback, you have to constrain your audience parameters around variables that actually dictate financial stress. We defined our target audience not as generic web users, but as middle-income earners living in urban centers with household incomes below median thresholds.
A common mistake at this stage is keeping parameters broad to capture a larger audience. Broad parameters wash out the exact demographic signals where objections live. Narrow your parameters to a specific household type, income band, and geographic density before touching any simulation software.
Step 2: Generate Structured Questionnaires Grounded in Real Census Data
Moving from a rough hypothesis to a testable objection requires a structured questionnaire rather than open-ended chat prompts. Unstructured prompts invite the language model to invent opinions, whereas structured questions force respondents to choose between conflicting financial pressures.
We took our debt consolidation hypothesis and translated it into a multi-choice questionnaire format focused on liquidity risks and credit score penalties.
The mechanism that prevents the simulation from drifting into polite agreement is anchoring the questionnaire to empirical population baselines. According to technical documentation from the U.S. Census Bureau, the American Community Survey 1-year Public Use Microdata Sample files capture data on approximately 1 percent of the United States population, maintaining disclosure protection so individual housing units remain unidentifiable.
When software builds a questionnaire for a specific demographic segment, it draws from these underlying microdata records to ensure the simulated responses reflect real economic distributions rather than generalized AI assumptions.
We used MoeVox to ingest our target audience parameters and our draft questionnaire items. The platform generated a structured set of questions that mapped directly onto variables found in the microdata files, including occupation categories, housing tenure, and wage brackets.
Writing questions without this demographic tethering produces answers that sound reasonable in a conference room but fail under the financial constraints of real households. Let the structural distribution of the census data dictate the scale of your questionnaire items.
Step 3: Run Simulations Across Diverse Behavioral and Demographic Segments
Running the simulation requires passing your structured questionnaire through a population model that mirrors the socioeconomic diversity of your target market. If your simulation engine relies on a single generalized prompt persona, you will only hear one voice echoing your own biases.
We ran our questionnaire through a simulated population model built from 100,000 real U.S. demographic records drawn from the synthetic census demographic survey dataset generator dataset.
This dataset covers a full range of population and housing unit responses collected on individual survey forms for that one percent subsample, incorporating variables such as age, race, gender, income, and behavioral trait labels.
The execution step involves submitting the questionnaire to the simulation engine, which distributes the questions across the demographic segments defined in the microdata records.
Our run produced distinct response clusters for urban renters versus suburban homeowners. The urban cohort flagged immediate cash flow interruptions as their primary objection to our consolidation advice, while the suburban cohort raised credit score volatility as their main concern.
A critical failure mode during simulation runs is ignoring minority demographic representation within the broader sample. If your parameters lump distinct income tiers together, the resulting objection frequencies will smooth over the exact friction points that trip up your readers. Check that your simulation pulls distinct sample records across all designated demographic cells before moving on to the analysis phase.
Step 4: Extract Quantifiable Response Distributions and Objection Frequencies
Raw simulation outputs are just digital noise until you pull out the response distributions and map the exact frequency of each reader objection. Without a numerical breakdown, you are back to guessing which skepticism matters most for your draft.
We looked at the raw output files from our simulation run and sorted the responses by objection type and demographic segment.
The urban renter cohort returned a sixty percent rejection rate driven entirely by immediate liquidity fears, while the suburban cohort showed a forty percent objection rate centered on credit score drops.
Those numbers replaced our editorial hunches with clear percentages that told us where the draft needed heavy defense.
A frequent misstep when reading these distributions is treating every voiced objection with equal weight. Not all complaints carry the same publishing risk. If a minor objection appears in only five percent of the responses, you do not need to rewrite your core argument to appease it. Focus your edits on the friction points that dominate the upper quartiles of your distribution output.
Step 5: Analyze Driver Rankings to Identify Core Friction Points and Skepticism
Once you have the response distributions, you need to analyze the underlying drivers that pushed respondents to reject your claims. A frequency count tells you how many people object, but the driver ranking tells you why they hold that specific skepticism.
We mapped our survey results to uncover which underlying variables triggered the highest levels of distrust in our debt consolidation thesis.
For our urban demographic segment, the primary driver was not interest rates, but the fear of hidden penalties that would trigger a cash flow crisis within the first month.
That finding forced us to cut three paragraphs of theoretical financial advice and replace them with a transparent breakdown of fee structures.
If you skip the driver ranking and jump straight from frequency counts to rewriting your content, you end up addressing symptoms rather than the root cause of the reader's resistance. Look at which variables correlate most strongly with negative sentiment scores, and build your content countermeasures around those specific pressure points.
Step 6: Translate Empirical Survey Datasets into Authoritative SEO and GEO Content
Turning survey datasets into high-performing search content means weaving concrete demographic data directly into your paragraphs instead of hiding behind vague claims about what readers think. Generative engines and skeptical readers alike ignore broad assertions, but they index specific numbers and clear methodological evidence.
We took the objection frequencies and driver rankings from our simulation and wove them straight into the revised personal finance guide.
Instead of writing that readers worry about fees, we stated that sixty percent of urban renters flagged liquidity risks as the primary barrier to debt consolidation.
That shift transformed our draft from a standard opinion piece into an authoritative resource backed by verifiable demographic metrics.
When you publish content grounded in these datasets, your pages provide the exact empirical depth that search algorithms and AI engines look for when citing primary sources.
Check your final draft against the initial objection hypothesis to ensure every major skepticism point is answered with a data-backed counter-argument. If your revisions still rely on generalized statements rather than the specific distributions from your simulation run, the content will fail to convince the readers you are trying to reach. Verify that your numbers match your source datasets before you hit publish, and let the empirical friction guide every word of your pushback strategy.